Archived learning note: Sequentia is my hands-on implementation of Andrej Karpathy's makemore project from Neural Networks: Zero to Hero.
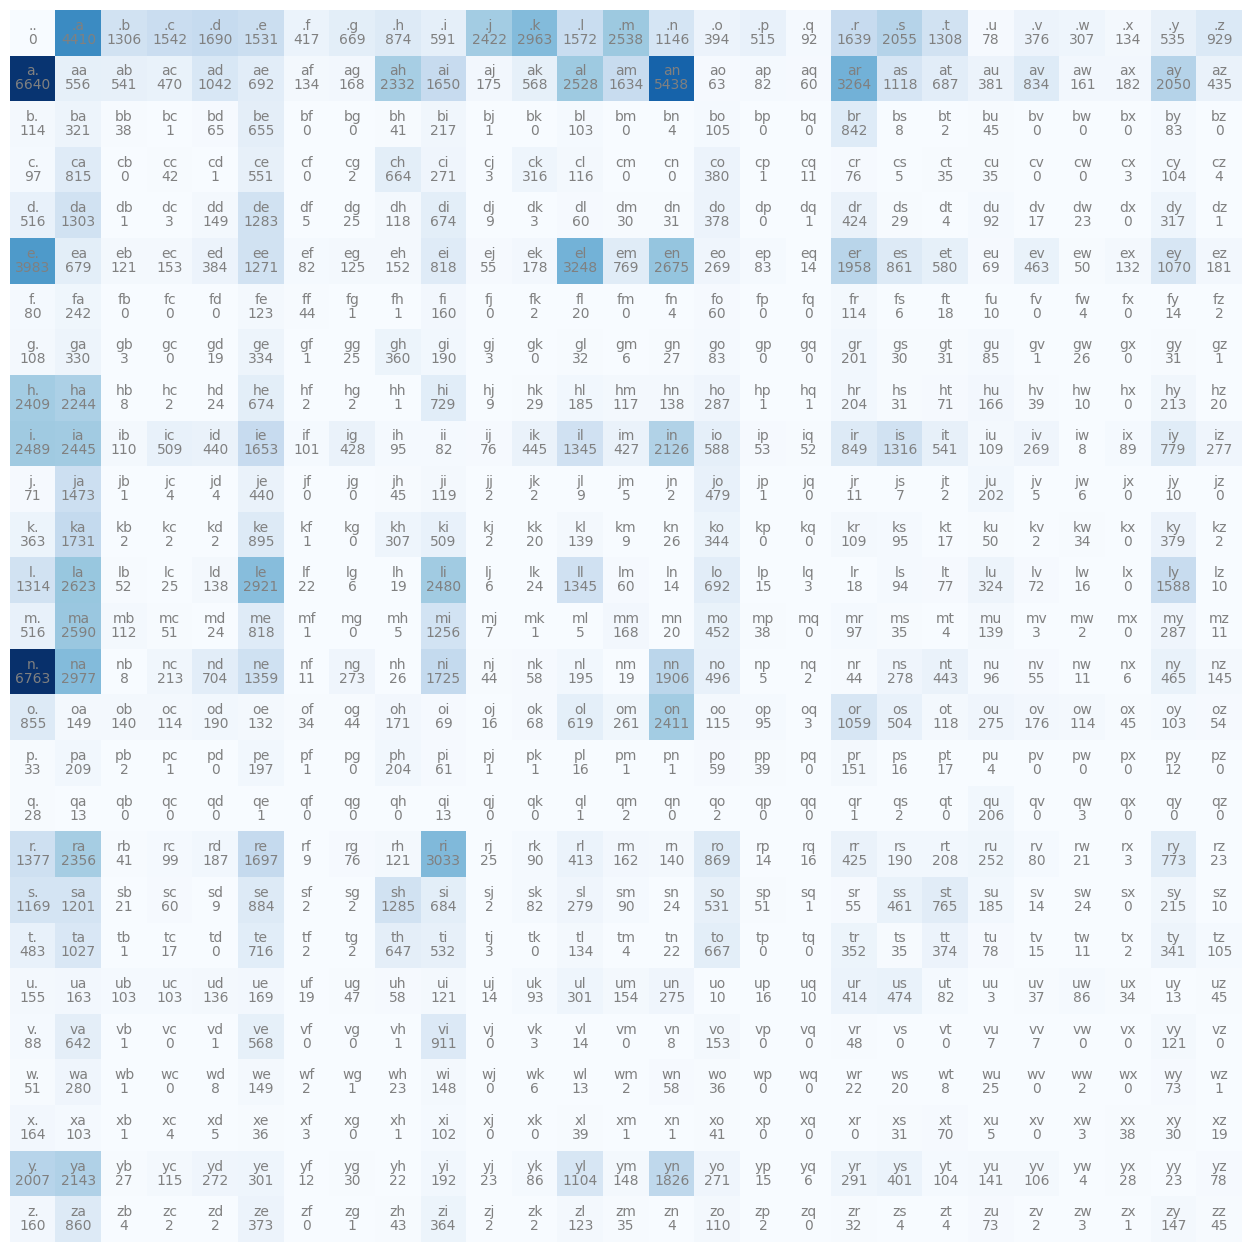
I used the names.txt dataset from makemore to work through character-level language modelling. The first stage compared a count-based bigram model with a gradient-based neural version. The second stage used a multilayer perceptron based on the approach in Bengio and colleagues' A Neural Probabilistic Language Model.
What remains
- My Sequentia repository.
- Karpathy's first makemore lecture, covering bigram language models.
- Karpathy's second makemore lecture, covering multilayer perceptrons.
The previous two-part version of this page was a long follow-along of those lectures. I have combined and shortened it here so the original teachers remain the source for the full explanations.